How to Convert a Photo or Scan to Word: A Practical OCR Checklist
Prepare a document photo for OCR, convert it to editable Word, and check blur, skew, glare and critical text before using the result.
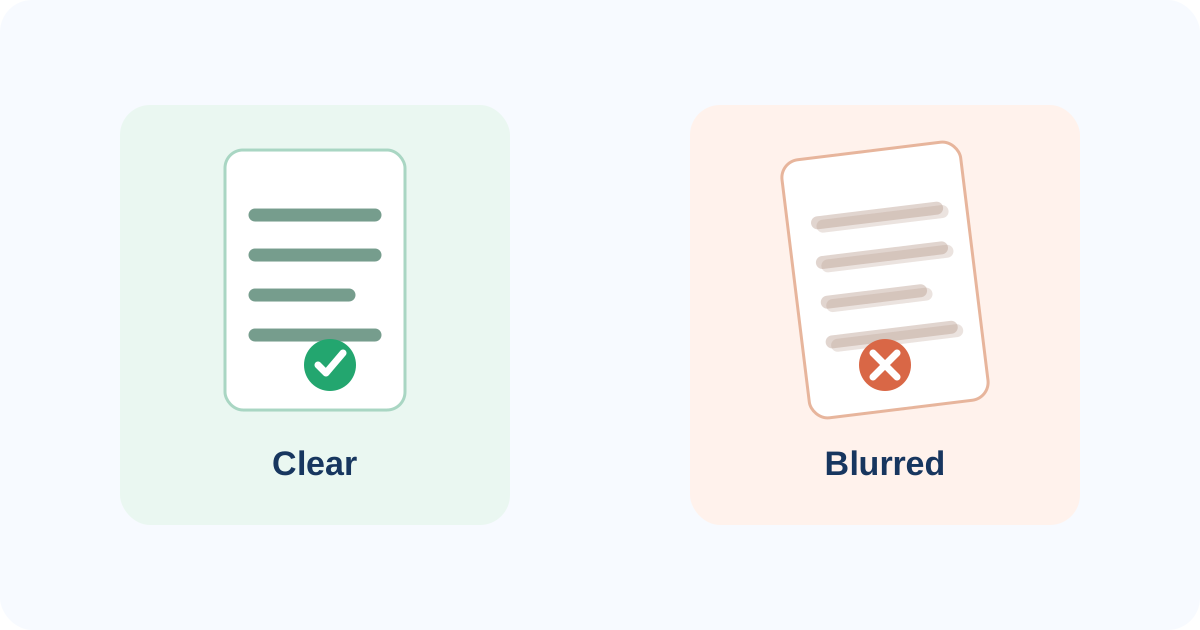
A photo of a document can be converted to editable Word, but OCR can only work with the detail that is actually visible in the image.
If the page is blurry, tilted, cut off, badly lit or too small, changing OCR settings later may not solve the real problem.
The best workflow is:
capture a clean page → choose the right OCR language → convert → verify the Word file.
That sequence is more reliable than repeatedly rerunning OCR on the same poor image.
Start with the image, not the OCR setting
Before uploading a photo or scan, check five things:
- the whole page is visible;
- the text is sharp when you zoom in;
- the page is reasonably straight;
- there is no strong glare or shadow across the text;
- the smallest important text is large enough to read.
These checks matter because OCR is image recognition.
Tesseract's documentation specifically identifies skew, noise, uneven backgrounds and low-quality source images as factors that can reduce recognition quality.
Google's Document AI documentation also treats blur, small text, glare and other image-quality defects as measurable OCR problems.
Photo and scan: what is the difference for OCR?
A scanner and a phone camera both produce images.
The difference is usually how controlled the capture is.
A flatbed or document scanner normally keeps the page:
- flat;
- evenly lit;
- straight;
- consistently framed.
A phone photo can be just as usable, but it is easier to introduce:
- perspective distortion;
- motion blur;
- glare;
- shadows;
- cropped edges;
- uneven focus.
So the question is not "photo or scan?" as much as "is the image clear enough for recognition?"
Problem 1: blur
Blur removes character detail.
When letters lose their sharp edges, OCR has less information to distinguish similar shapes.
For example, depending on the font and source quality:
- 0 and O;
- 1 and I;
- 5 and S;
- rn and m;
can become harder to distinguish.
If the image is visibly out of focus, recapturing it is often faster than correcting a long list of OCR errors later.
Better capture
Hold the camera steady, use enough light, and make sure the text is sharp before you take the photo.
ABBYY's current document-photo guidance also recommends even lighting, stable capture and sharp focus for OCR-oriented photographs.
Problem 2: skew and perspective
A document does not need to be perfectly level, but strong tilt can hurt line detection.
Tesseract notes that skew can significantly reduce line-segmentation quality.
Phone photos can also introduce perspective: the top of the page may appear narrower than the bottom if the camera is held at an angle.
Better capture
Keep the camera as parallel to the document as practical.
Make sure all four corners of the page are visible.
If the page is already photographed, straighten or crop it before OCR when your image editor allows that.
Problem 3: glare and shadows
Glossy pages, plastic covers and overhead lights can create bright areas that hide parts of letters.
Heavy shadows can do the opposite by merging text into a dark background.
ABBYY recommends bright, even lighting and avoiding glare when photographing documents.
Better capture
Move the document or light source until the text is evenly visible.
Do not rely on flash if it creates a bright reflection over the content.
Problem 4: crop and cutoff
OCR cannot recognize information that is outside the image.
This sounds obvious, but document photos are often cropped too tightly around the text.
Important content can disappear at:
- page edges;
- headers;
- footers;
- table columns;
- signatures;
- reference numbers.
Better capture
Include the whole page first.
You can crop excess background later.
Do not cut into the page merely to make the document fill the screen.
Problem 5: tiny text
A page may look readable when viewed as a whole, but small text can become too soft for OCR.
This is common with:
- fine print;
- footnotes;
- forms;
- tables;
- low-resolution screenshots.
Tesseract's documentation notes that image scale and text size can materially affect recognition.
Better capture
Move closer while keeping the entire page in frame, or use a higher-quality source image.
Do not assume digital upscaling can recreate detail that was never captured.
How to convert the image to Word in PDFixo
PDFixo's Image to Word tool is designed for photos and scans.
1. Choose the image
Use the clearest available source.
If you have multiple versions of the same page, choose the one with the least blur, glare and skew.
2. Start with Auto
PDFixo presents Auto as the default choice for most documents.
If you know the document is specifically English, Hindi or mixed Hindi + English, you can choose that language mode instead.
Language selection helps the recognizer interpret characters.
It does not repair a poor image.
For deeper language guidance, see Hindi + English OCR: Which Language Mode Should You Choose for Mixed Documents?.
3. Run the conversion
The current Image-to-Word page states that OCR and Word creation run locally in the browser for this tool.
After processing, download the DOCX.
4. Compare the Word file with the image
Do not stop at "the conversion finished."
Check the output against the source.
Focus on:
- names;
- dates;
- phone numbers;
- amounts;
- IDs and reference numbers;
- headings;
- table values;
- small text.
A document can be mostly correct and still contain one important recognition error.
Why language choice cannot fix a bad photo
OCR language and image quality solve different problems.
Language mode tells the recognizer what character patterns to expect.
Image quality determines whether those characters are visible clearly enough to interpret.
If a Hindi page is badly blurred, choosing Hindi is still the correct language decision—but the blur remains.
If an English page has glare across a number, choosing English does not restore the missing strokes.
That is why P07 begins with capture quality rather than OCR settings.
What about handwriting?
Do not assume ordinary document OCR will treat handwriting like clean printed text.
Some OCR systems support handwriting recognition in specific products or models, but a printed-text conversion workflow should not be presented as a universal handwriting solution.
For important handwritten content, verify what the current tool actually recognizes before relying on the output.
What about tables?
Tables add another layer of difficulty.
OCR may recognize the words correctly but still reconstruct rows, columns or cell spacing differently in Word.
That is not necessarily a text-recognition failure.
If the table matters, compare:
- row order;
- column alignment;
- values;
- headings;
- totals.
When rescanning is better than correcting OCR
Recapture the source when:
- several words in every line are wrong;
- text is visibly blurred;
- strong glare hides content;
- the page is badly skewed;
- important content is cut off;
- small print is unreadable even before OCR.
A better source can save more time than repeatedly fixing recognition errors.
If your source is already a PDF
Do not convert a scanned PDF into images just to use Image-to-Word.
Use PDFixo PDF to Word for PDF sources.
That avoids an unnecessary format change and keeps the workflow aligned with the source you actually have.
For the full scanned-PDF route, see How to Convert a Scanned PDF to Editable Word Without Guessing the OCR Mode.
The shortest useful checklist
Before OCR:
Sharp. Straight. Evenly lit. Fully visible. Readable at zoom.
Then:
Choose language → convert → verify critical text.
Next step
Open PDFixo Image to Word, use the clearest photo or scan you have, and verify the resulting DOCX against the original image before relying on important details.
If the conversion is poor even with a clean source, see OCR Accuracy Problems: How Blur, Skew, Contrast and Scan Quality Affect Text Recognition.
Found an unclear step or an outdated detail? Tell our support team.